An AI SRE is an AI agent, or a coordinated group of agents, designed to perform defined site reliability engineering tasks using live operational context, approved tools and governed workflows.
Unlike a chatbot that summarizes an alert, an AI SRE can investigate an incident across monitoring, observability, ITSM, cloud and network systems. Depending on its permissions, it can recommend a response, execute an approved runbook or remediate the issue and document what it did.
The important changes will not be the removal of human SREs, but a new division of labor. AI agents will handle more repetitive investigation and execution, while people retain responsibility for reliability strategy, engineering judgment, governance and unfamiliar failure modes.
What does an AI SRE do?
An enterprise AI SRE can support a reliability workflow from detection through resolution in six stages.
- Detect and qualify incidents by ingesting alerts, events, logs, metrics, traces and tickets, then separating actionable incidents from noise.
- Collect context by identifying affected services, infrastructure, dependencies, recent changes, ownership and relevant runbooks.
- Investigate by forming and testing hypotheses across multiple tools rather than handing responders another dashboard.
- Recommend or act by suggesting the next step, requesting approval or executing an action within predefined limits.
- Verify recovery by confirming that service health and user impact have returned to acceptable levels.
- Record the decision trail by updating the incident record with evidence, actions, results and approvals.
This closes what Fabrix.ai describes as the last-mile problem in IT operations. Monitoring tools can reveal symptoms, but teams still have to connect the evidence and act.
AI SRE vs. AIOps vs. an SRE copilot
| Capability | Traditional AIOps | SRE copilot | AI SRE |
|---|---|---|---|
| Correlates operational signals | Yes | Sometimes | Yes |
| Answers natural-language questions | Limited | Yes | Yes |
| Conducts multi-step investigations | Workflow-dependent | Usually assists a person | Yes, within its scope |
| Uses operational tools | Through integrations | Usually read-oriented | Read and approved write actions |
| Executes remediation | Often rules-based | Usually no | Yes, when authorized |
| Requires agent governance | Limited | Moderate | Essential |
AIOps remains part of the foundation. It applies analytics and machine learning to operational data. An SRE copilot helps a person interpret that data. An AI SRE adds goal-directed investigation, tool use and controlled action.
The progression is therefore not simply “better AIOps.” It is a move from AIOps to AgentOps, where enterprises must operate and observe the agents themselves.
How AI agents change reliability work
Routine triage becomes machine-led
AI agents can gather evidence before an engineer joins an incident. Instead of opening multiple consoles and reconstructing a timeline, the responder receives a working hypothesis, affected-service map and recommended action.
On-call shifts toward exception handling
Humans will remain essential when evidence conflicts, customer impact is ambiguous or remediation carries material risk. But they should spend less time on repetitive enrichment, ticket updates and known failure patterns.
Runbooks become executable policies
A static runbook tells an engineer what to do. An agent-ready runbook also defines prerequisites, permissions, verification checks, rollback conditions and escalation points. Reliability teams will increasingly maintain these policies as production assets.
SREs gain responsibility for agent reliability
Teams will need to evaluate whether an agent used current data, selected the correct tool, stayed within scope and produced the intended result. Agent success rate, approval rate, rollback rate and unsafe-action attempts will complement established measures such as SLO attainment and MTTR.
Why operational context matters more than a general-purpose model
An AI SRE cannot make dependable decisions from an alert description alone. It needs current topology, service ownership, dependencies, change history, telemetry, tickets and policy context.
Fragmented or stale data can produce confident but incorrect conclusions. Enterprises should therefore treat agent-ready operational data as a prerequisite, not an integration task to address after deployment.
For hybrid and multi-vendor environments, this context must span existing tools without requiring a wholesale replacement of the operational stack.
Governed autonomy is the enterprise requirement
The question is not whether an AI SRE is fully autonomous. The useful question is what level of agency is appropriate for this task.
A practical control model includes the following safeguards.
- Read-only access by default
- Role-based permissions and scoped credentials
- Approved tools, actions and targets
- Human approval for higher-risk changes
- Confidence or evidence thresholds
- Pre-action checks and post-action verification
- Rollback and escalation paths
- Complete audit trails
- Agent performance, cost and behavior monitoring
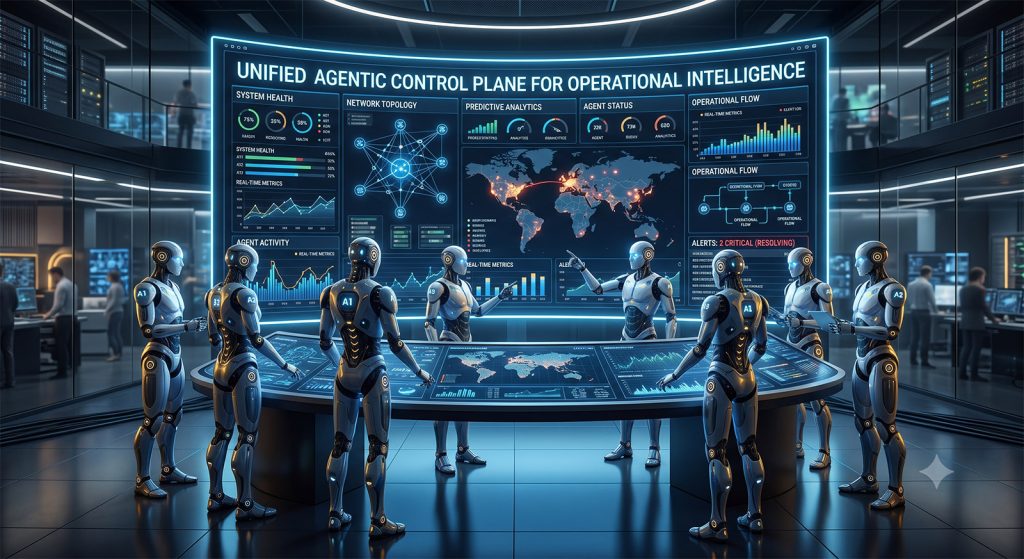
These controls require a unified agentic control plane rather than isolated agents with separate permissions and logs.
How to prepare for an AI SRE
Start with a bounded, measurable workflow rather than an open-ended mandate.
- Choose a high-volume incident type with a known diagnostic path.
- Map the required telemetry, topology, tickets and change data.
- Define permitted actions and mandatory approvals.
- Establish a baseline for investigation time, MTTR and escalations.
- Run the agent in observation or recommendation mode.
- Validate its evidence and decisions against experienced operators.
- Expand autonomy only after performance is repeatable and auditable.
Fabrix.ai positions AI SRE agents as part of an agentic operational intelligence platform that works across existing enterprise tools. The company reports outcomes including more than 70% MTTR reduction, more than 85% alert-noise reduction and more than 90% less investigation time; results will depend on each environment, workflow and deployment.
People set policy and agents execute within it
AI SRE should not mean unattended automation everywhere. It should mean that routine operational work can move at machine speed while human teams retain control over objectives, risk and exceptions.
Enterprises that prepare their data, runbooks and governance now will be better positioned to use AI agents as dependable reliability collaborators rather than just another source of recommendations.
Ready to evaluate an AI SRE on your existing operational stack?
Frequently Asked Questions
What is an AI SRE?
An AI SRE is an AI agent, or a coordinated group of agents, that performs defined site reliability engineering tasks using live operational context, approved tools and governed workflows. It can investigate incidents across monitoring, observability, ITSM, cloud and network systems and, depending on its permissions, recommend a response, run an approved runbook or remediate the issue.
How is an AI SRE different from AIOps?
AIOps applies analytics and machine learning to operational data, mainly to correlate signals. An AI SRE adds goal-directed, multi-step investigation, tool use and controlled action, including approved write actions and remediation when authorized.
How is an AI SRE different from an SRE copilot?
An SRE copilot helps a person interpret data and is usually read-oriented. An AI SRE conducts multi-step investigations within its scope, uses operational tools and can execute remediation when authorized, which is why it needs stronger agent governance.
Will AI SREs replace human site reliability engineers?
No. The main change is a new division of labor: AI agents handle more repetitive investigation and execution, while people keep responsibility for reliability strategy, engineering judgment, governance and unfamiliar failure modes.
What controls does an enterprise AI SRE need?
A practical control model includes read-only access by default, role-based permissions and scoped credentials, approved tools and actions, human approval for higher-risk changes, evidence thresholds, pre-action checks and post-action verification, rollback and escalation paths, complete audit trails and monitoring of agent performance, cost and behavior.
How should a team start with an AI SRE?
Start with a high-volume incident type that has a known diagnostic path, map the data it needs, define permitted actions and approvals, set a baseline for investigation time and MTTR, run the agent in recommendation mode, validate it against experienced operators and expand autonomy only once results are repeatable and auditable.